
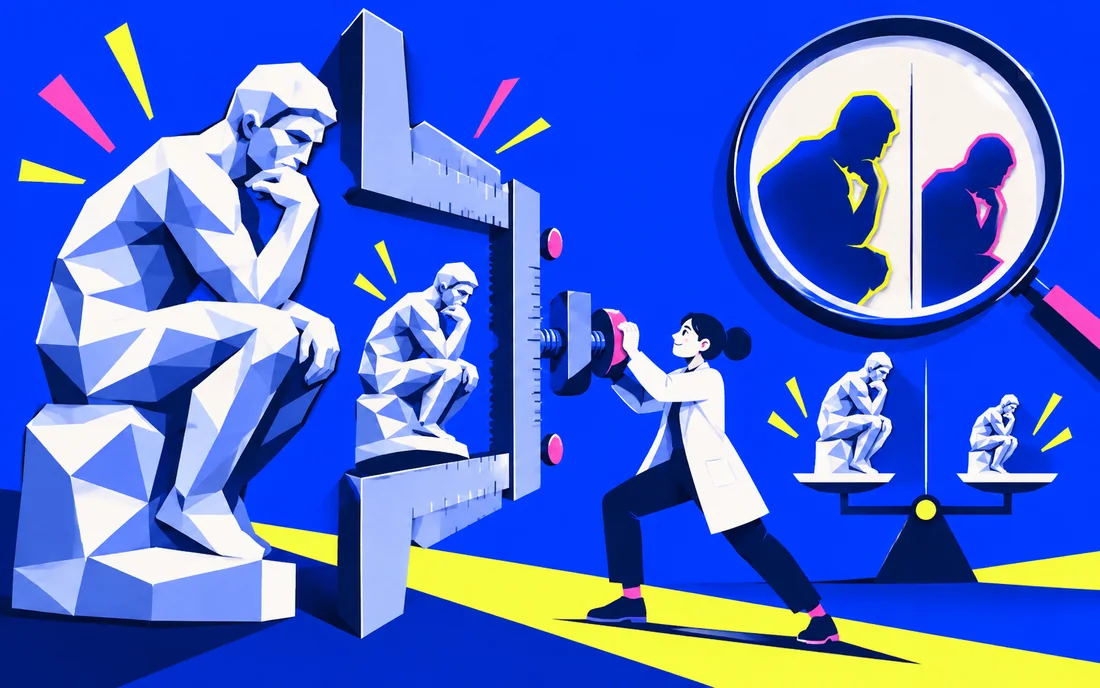
The quick read
- Run the original and quantized versions on representative inputs.
- For a local assistant, fitting comfortably in memory may avoid severe slowdowns.
What gets smaller
A model stores numerical values. Quantization represents some of those values with fewer bits, potentially reducing memory requirements while introducing approximation. The practical effect varies by method, model and hardware; a smaller file alone does not prove a better experience.
Compare the same work
Run the original and quantized versions on representative inputs. Include difficult extraction cases, unfamiliar terms and the longest documents you expect. Measure correctness alongside memory use and response time. A change that barely affects an average score may still matter for one critical field.
Choose an operating point
For a local assistant, fitting comfortably in memory may avoid severe slowdowns. For another task, a loss of accuracy may outweigh that benefit. Record the model version and quantization format with your results so the comparison can be reproduced. Keep a small regression set for future updates. The goal is a model that meets the required quality on available hardware, rather than the smallest model file you can find.
Sources & notes
AI-assisted editorial content checked against the linked sources.
huggingface.co — official reference
Sources reviewed for the September 2026 launch edition.