
The quick read
- A support question about a package arriving late might be close to a document about delivery delays.
- Keep the embedding model and preprocessing consistent when comparing stored vectors with new queries.
The basic idea
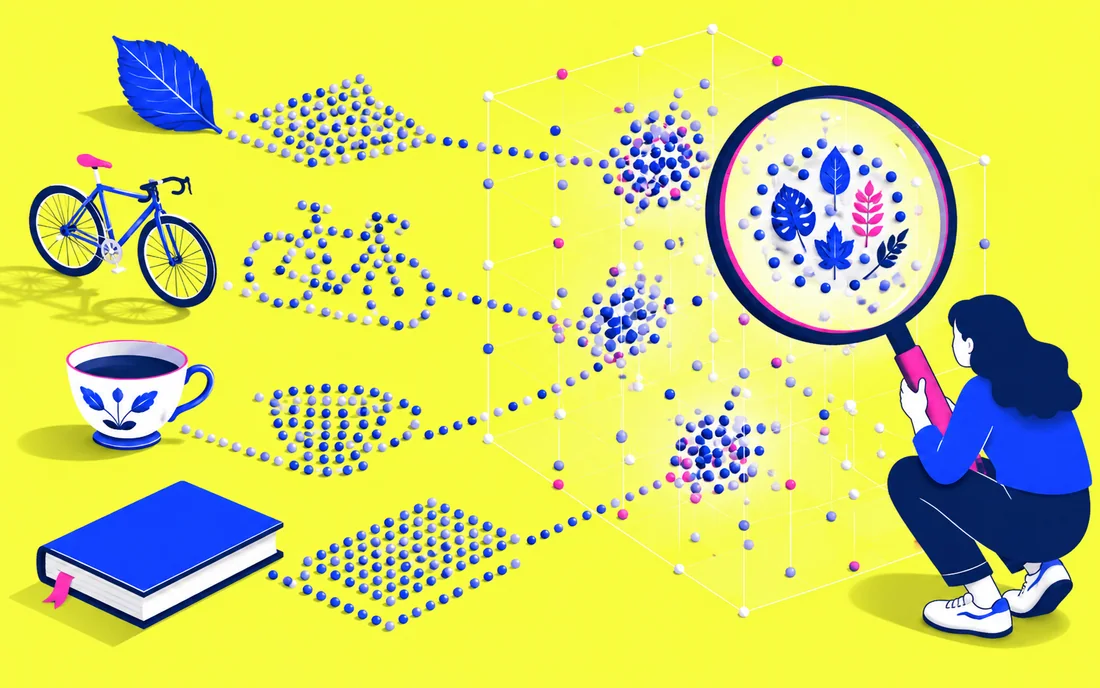
An embedding model maps an input, such as a sentence, to a list of numbers. Nearby vectors can represent related meanings according to what the model learned. This makes it possible to look for relevant material even when the query does not repeat the exact words in a document.
A useful example
A support question about a package arriving late might be close to a document about delivery delays. That relationship can help a search system find a useful answer. It does not prove that the document applies to the customer’s country, shipping service or order date. Similarity is one retrieval signal, not a complete decision rule.
Use them carefully
Keep the embedding model and preprocessing consistent when comparing stored vectors with new queries. Test ordinary user wording, unusual terminology and examples that should not match. Attach useful metadata, such as language and document version, so retrieval can apply constraints beyond similarity. The practical goal is to improve the set of evidence a person or model sees. A high similarity score should lead to closer inspection of a candidate source, rather than automatic acceptance of its contents.
Sources & notes
AI-assisted editorial content checked against the linked sources.
Sources reviewed for the September 2026 launch edition.